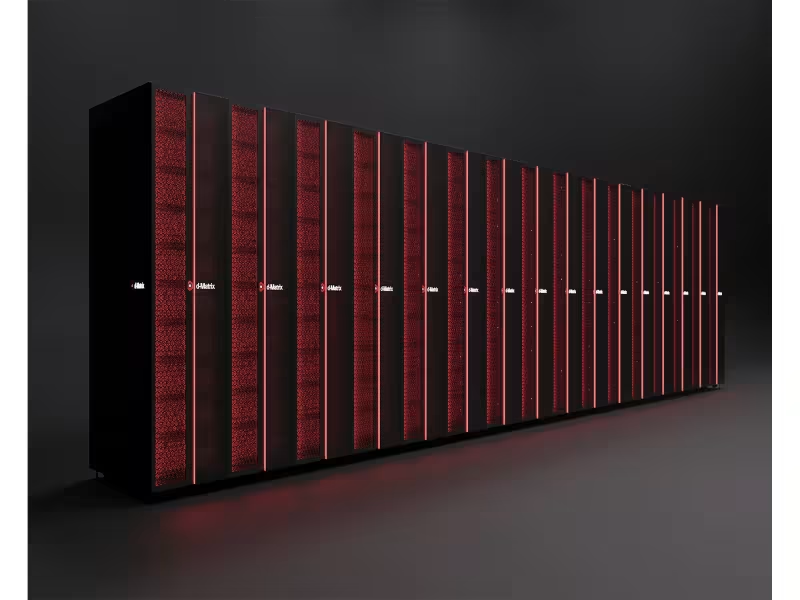
San Jose – October 12, 2026 -- d-Matrix has launched Squadron, a fleet of multi-rack inference systems that scale to 1,024 interconnected Corsair XPUs and deliver megawatts of compute for latency-sensitive AI workloads. The systems are shipping to priority customers, and the underlying Corsair servers and SquadRacks are now generally available.
Squadron clusters scale to 16 racks and run on air cooling
A Squadron cluster combines up to 16 SquadRacks, each a single rack holding eight servers. Clusters are interconnected with d-Matrix JetStream NICs and managed with Aviator software.
The systems are air-cooled and built on industry standards. d-Matrix says customers can install them in existing data centers without liquid cooling or major buildouts. Customers can start with a single Corsair server, move to a full SquadRack, or scale to a multi-rack cluster on the same architecture.
Arista, Broadcom and Supermicro co-developed the platform
d-Matrix developed Squadron with Arista, Broadcom and Supermicro and has already deployed it in its Arizona data center for internal research and development. Target users include AI labs, enterprises and sovereign organizations running coding, personal agent, cybersecurity and high-frequency trading applications.
Supermicro CEO Charles Liang said the collaboration shows the company can deliver AI infrastructure through its Data Center Building Block Solutions, with faster time-to-online for inference workloads. d-Matrix founder and CEO Sid Sheth, who unveiled Squadron in his OCP Global Summit keynote at the San Jose Convention Center, described the launch as a shift from chip vendor to data center compute infrastructure business. “The wait is over,” he said.
AFD demo reaches 845 tokens per second per user on mixed GPU-XPU hardware
Squadron can run full models exclusively on Corsair XPUs. It also supports heterogeneous setups that split work between GPUs and XPUs, an approach called disaggregated compute.
Sheth disclosed that d-Matrix has implemented Attention-FFN Disaggregation (AFD) on a Squadron system paired with GPU servers. With Experts/FFN offloaded to Corsair racks, the heterogeneous system generated 845 tokens per second per user. With 64 concurrent users, the setup delivered total throughput of 20,415 tokens per second.
d-Matrix says it is the first to show AFD running on commercially available silicon, after the approach was discussed across the industry mainly in theory.
Live AFD demos run at OCP booth C82 on Oct. 14 and 15
d-Matrix researchers will present the AFD demo at booth C82 on Wednesday, Oct. 14, at 11am PT and 2pm PT, and on Thursday, Oct. 15, at 11am PT.